What Is Jev? The AI Model That Makes Decisions Instead of Writing
Most AI products ask a language model to generate an answer, even when the
application only needs a decision. A support router does not need a paragraph.
It needs billing, technical, or sales, plus enough uncertainty information
to decide whether a person should review the result.
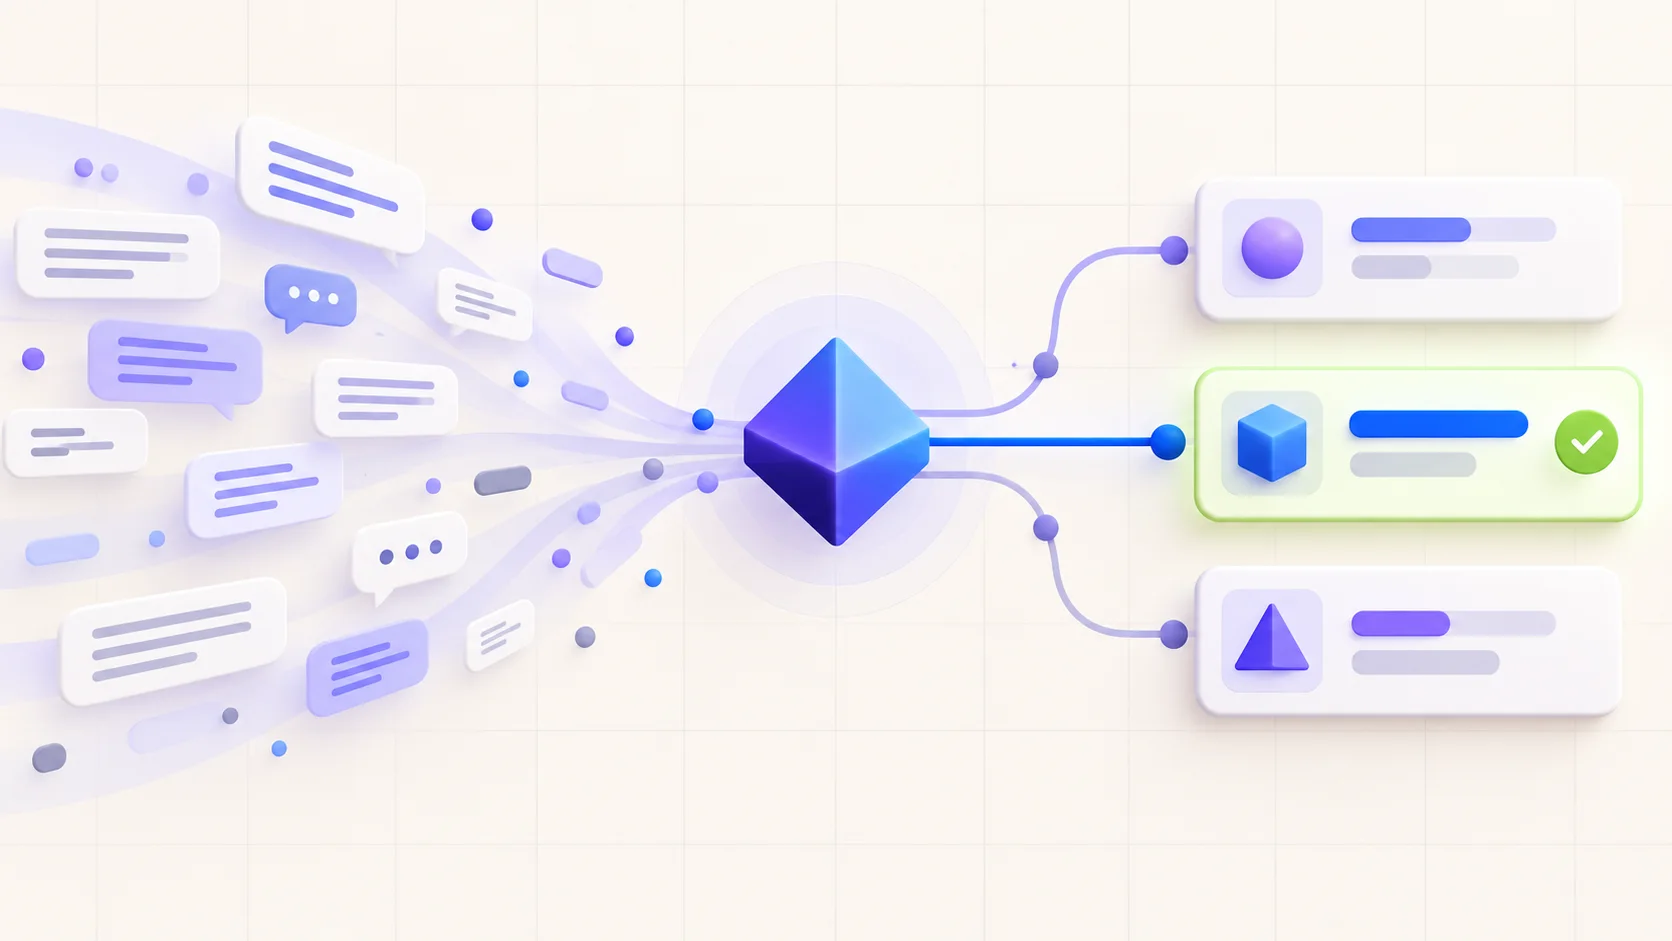
Jev is a new model from TypeSafe AI built around that distinction. It accepts context and focused questions, then returns typed choices, scores, and probabilities rather than free-form text. TypeSafe calls it its first System One Model: a model designed to make bounded decisions inside software.
The short answer
Jev is not a chatbot and it does not write prose. You give it:
- a state containing text, JSON, or other application context;
- one or more focused questions;
- the answer shape and, where relevant, the permitted options.
It returns structured decisions your code can inspect and use. A single request can classify a user's intent, estimate urgency, and check whether the request needs human review.
That makes Jev relevant to:
- intent classification;
- support-ticket routing;
- tool and model selection inside AI agents;
- content moderation and policy checks;
- document or lead scoring;
- relevance and grounding checks;
- low-latency decisions in interactive applications.
Jev was introduced on September 15, 2026. It is still a new commercial model, so production teams should evaluate it against their own data rather than treating early launch results as universal proof.
Why use a decision model instead of an LLM?
Large language models are optimized for flexible output. That is useful when an application needs an explanation, summary, plan, conversation, or code. It is often unnecessary when the application already knows the available outcomes.
Consider this support message:
I was charged twice for my subscription. Please refund the duplicate charge.
A conventional LLM workflow may ask for JSON, wait while the model generates tokens, parse the response, validate its schema, and retry if the output is invalid. Yet the useful decision may only be:
{
  "department": "billing",
  "refund_requested": true,
  "urgency": "high"
}
Jev is designed to score those predefined answers directly. Its output is bounded by the types and options supplied by the application. This removes the need to parse prose or recover from a fabricated label that was never part of the schema.
It does not remove the possibility of a wrong decision. Type safety answers "Is this output structurally valid?" Accuracy answers "Did the model understand the situation correctly?" Production software needs to test both.
How Jev works
TypeSafe's official API exposes one main decision endpoint. A request contains a shared state and a collection of named questions. Jev evaluates those questions and returns a typed answer for each one.
The model supports three question shapes:
| Type | Purpose | Example |
|---|---|---|
| Choice | Select one permitted option | Which team should handle this ticket? |
| Score | Place the state on an ordered scale | How urgent is this request? |
| Noul | Return a yes/no probability | Does the customer explicitly request a refund? |
"Noul" is TypeSafe's name for the binary probability type. Multiple questions can be evaluated against the same state in one call.
A simplified request looks like this:
{
  "model": "jev-latest",
  "state": "I was charged twice. Please refund one payment today.",
  "questions": {
    "department": {
      "type": "choice",
      "instructions": "Which team should handle this request?",
      "criteria": {
        "billing": "Charges, invoices, and refunds",
        "technical": "Product errors and outages",
        "sales": "Plans and purchasing questions"
      }
    },
    "refund_requested": {
      "type": "noul",
      "instructions": "Does the customer explicitly request a refund?"
    },
    "urgency": {
      "type": "score",
      "instructions": "How urgent is this request?",
      "criteria": ["can wait", "this week", "today"]
    }
  }
}
Your application can then apply ordinary rules:
if (result.department.choice === 'billing' && result.department.confidence > 0.9) {
  routeToBilling();
} else {
  requestHumanReview();
}
The important product pattern is not "let AI control everything." It is "let the model make a narrow judgment, then let code enforce permissions, thresholds, and actions."
Jev vs LLMs vs application rules
Jev does not replace every part of an AI stack.
| Need | Best starting point |
|---|---|
| Generate an explanation, email, or summary | Generative LLM |
| Make a bounded choice from known options | Jev or another evaluated classifier |
| Perform exact calculations | Normal code |
| Enforce permissions and business invariants | Normal code and database rules |
| Decide whether uncertainty needs review | Model score plus application thresholds |
| Handle a complex, open-ended plan | Reasoning model with tools and oversight |
A useful agent may combine all three layers:
- Jev classifies the request and chooses an allowed tool.
- Application code checks identity, permissions, limits, and required approval.
- An LLM writes a response only if the workflow actually needs language.
This separation addresses part of the AI last-mile problem: models create value only when their output fits a reliable workflow. It also complements good AI agent context design, because a decision model is only as useful as the state the application provides.
The clearest use case: intent classification
Intent classification is a strong first test because the available routes are usually known in advance.
For example, a product may need to distinguish between:
- account access;
- billing and refunds;
- bug reports;
- product questions;
- cancellation risk;
- sales opportunities;
- spam or irrelevant messages.
The application can send the incoming message once and ask several questions about it. High-confidence, low-risk cases can be routed automatically. Ambiguous or sensitive cases can stay in a review queue.
This is more useful than asking a model for a single label and ignoring uncertainty. A practical workflow should define:
- the permitted labels;
- examples and boundaries for each label;
- a confidence threshold based on labeled production data;
- a fallback when no option is reliable;
- an audit log connecting the decision to the original state;
- a correction mechanism when a person changes the route.
The same pattern can classify feedback, prioritize leads, select a retrieval strategy, or decide which specialist model should handle the next step.
What TypeSafe claims—and what has been tested
TypeSafe says Jev uses a new architecture, parallel sampling, and a training method called Reinforcement Learning for Calibrated Decisions (RLCD). The company reports that its launch workflows were substantially faster and cheaper than comparable generative-model calls. It also publishes the benchmark setup and important caveats on its workflow evaluation site.
Those numbers should be described as vendor results, not as guarantees for every application. Input length, geography, network latency, question design, and the difficulty of the labels can all change the outcome.
Independent evaluation is beginning to appear. A September 2026 study, Evaluating and Benchmarking the System One Model Jev, tested version 1.13.0 across 37 datasets and 346,009 requests. The authors found strong results across many classification and reasoning tasks at low reported cost, while also finding weaker behavior on low-resource languages, fine-grained or noisy labels, and rubric-based judgments.
Another study comparing Jev with LLMs as rubric judges found that Jev was often much faster and cheaper, but that all evaluated systems could make correlated mistakes. That matters because escalating a decision from one model to another does not automatically create an independent second opinion. See JEV vs. LLMs as Rubric Judges.
Does Jev really have "zero hallucinations"?
The safest interpretation is narrow: Jev cannot invent an output outside the
answer schema supplied by the application. If the choices are billing,
technical, and sales, it cannot return an unexpected fourth string.
That is a meaningful reliability advantage, but it is not the same as being factually infallible. Jev can still:
- choose the wrong valid option;
- assign high confidence to a wrong decision;
- react badly to irrelevant or misleading context;
- perform poorly when labels overlap;
- inherit errors from missing, stale, or biased state data.
The recent JevOut study demonstrates this distinction. Its authors found that short, natural-looking context additions could redirect decisions toward an incorrect option under an adversarial optimization setup. Similar sensitivity appeared in other evaluated decision systems, including a conventional Qwen model.
The lesson is not that decision models are unusable. It is that typed output reduces one failure class—invalid or unbounded output—while evaluation, context control, and human escalation remain necessary.
A production architecture for Jev
Treat Jev as one component in a controlled pipeline:
User or system event
        ↓
Permission-filtered state builder
        ↓
Jev: choice, score, and probability
        ↓
Application thresholds and business rules
        ↓
Automatic action OR human review OR generative LLM
        ↓
Outcome logging and correction
Keep secrets and provider calls on the backend. Do not let the client choose privileged tools or bypass subscription and role checks. Log the model version, question version, selected answer, confidence band, route, and corrected outcome without storing unnecessary sensitive content.
If the product may use several providers, place Jev behind the same backend abstraction as the rest of the model stack. Our guide to CompanyFabric explains why provider selection and fallback should stay outside the mobile release cycle.
When Jev is a good fit
Evaluate Jev when:
- the possible answers can be defined before the request;
- the decision happens frequently enough for latency and cost to matter;
- uncertainty can change the workflow;
- wrong decisions are reviewable or reversible;
- a generative answer would be discarded after parsing;
- you have labeled examples for testing thresholds.
Avoid making it the sole decision-maker when:
- the task requires original prose, code, or a long explanation;
- the answer space cannot be bounded meaningfully;
- one wrong decision can create irreversible harm;
- the application lacks reliable context and permissions;
- no one owns evaluation, monitoring, or corrections.
For choosing an initial workflow, use an impact-and-risk framework rather than starting from novelty. See How to Choose AI Use Cases and Measure Real ROI.
How to evaluate Jev before production
Build a private test set from the traffic your product actually receives. Include:
- common, obvious examples;
- ambiguous messages with overlapping labels;
- incomplete and multilingual requests;
- irrelevant background context;
- adversarial instructions inside user-controlled text;
- cases where the correct behavior is human review;
- high-impact actions that automation must never trigger directly.
Measure more than headline accuracy:
- accuracy and recall for each route;
- calibration by confidence band;
- false positives on sensitive actions;
- latency at realistic input sizes;
- end-to-end cost, including fallbacks;
- disagreement with human reviewers;
- performance after context or label wording changes.
Then choose thresholds from the cost of being wrong. A billing ticket routed to the wrong queue is inconvenient. A payment or account action triggered incorrectly can be damaging. Those decisions should not share the same automation threshold.
Why Jev matters
Jev's most important idea is not that every LLM should be replaced. It is that software often needs machine judgment without machine prose.
Generative models made natural language a powerful interface for people. Decision models are exploring a different interface: unstructured context in, bounded and probabilistic values out. If that interface holds up under broader production evaluation, it could make routing, verification, moderation, and agent control substantially easier to integrate.
For teams building AI products today, the practical next step is small: choose one bounded decision, compare Jev with your current rules or model, and measure where each one fails.
FAQ
Is Jev an LLM?
TypeSafe presents Jev as a System One decision model rather than a generative LLM. It processes language and structured state, but it returns typed choices, scores, and probabilities instead of generating text token by token.
Who created Jev?
Jev was created by TypeSafe AI, which released the model in early access on September 15, 2026.
Can Jev classify user intent?
Yes. Intent classification and routing are among its clearest use cases because the application can define the allowed intents and use confidence thresholds to decide between automation and review.
Can Jev replace an AI agent?
No. Jev can provide fast bounded judgments inside an agent. The surrounding application still needs context assembly, permissions, tools, business rules, monitoring, and often a generative model for user-facing language.
Is Jev open source?
The Jev service is commercial and accessed through TypeSafe's API. Open models with a similar typed-decision interface exist, but they are separate projects and should be evaluated independently.
Official and independent references
- TypeSafe AI: Introducing System One Models and Jev
- Official TypeSafe API documentation
- TypeSafe workflow evaluations
- Evaluating and Benchmarking the System One Model Jev
- JEV vs. LLMs as Rubric Judges
- JevOut: Natural Context Can Flip Decision Models
Continue with AI Skills for project-aware agent workflows, or see our guide to building reliable AI agent context before connecting model decisions to production actions.